

This tutorial shows how to classify code as readable or unreadable using benchmark datasets with ground-truth labels.
Key Takeaways:
- Download and prepare benchmark datasets for code readability evaluation
- Compare different LLM models (GPT-4, GPT-3.5, GPT-4 Turbo) for classification accuracy
- Analyze results with confusion matrices and detailed reports
- Get explanations for LLM classifications to understand decision-making
Notebook Walkthrough#
We will go through key code snippets on this page. To follow the full tutorial, check out the full notebook.

colab.research.google.com
Download Benchmark Dataset#
Configure Evaluation#
Run Code Readability Classification#
Run readability classifications against a subset of the data.
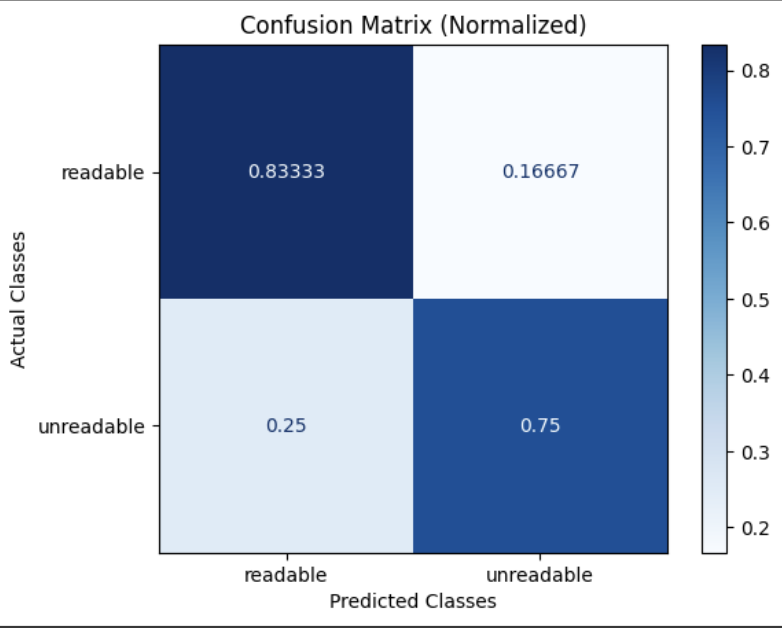
Evaluate Results and Plot Confusion Matrix#
Evaluate the predictions against human-labeled ground-truth readability labels.
Get Explanations#
When evaluating a dataset for readability, it can be useful to know why the LLM classified text as readable or not. The following code block runs the classifier with explanations included so that we can inspect why the LLM made the classification it did. There is a speed tradeoff since more tokens are being generated but it can be highly informative when troubleshooting.
Compare Models#
Run the same evaluation with different models: